Object Detection

Deep Learning and Computer Vision in R: A Practical Introduction

SSA ACT workshop - Object Detection

Weihao (Patrick) Li

RSFAS, ANU

Content summary

  • Overview of computer vision (CV)
  • reticulate and torch basics
  • Image classification, neural networks and Keras
  • Convolutional neural networks
  • Vision transformers
  • > Object detection
  • Image segmentation

Object detection

Object detection

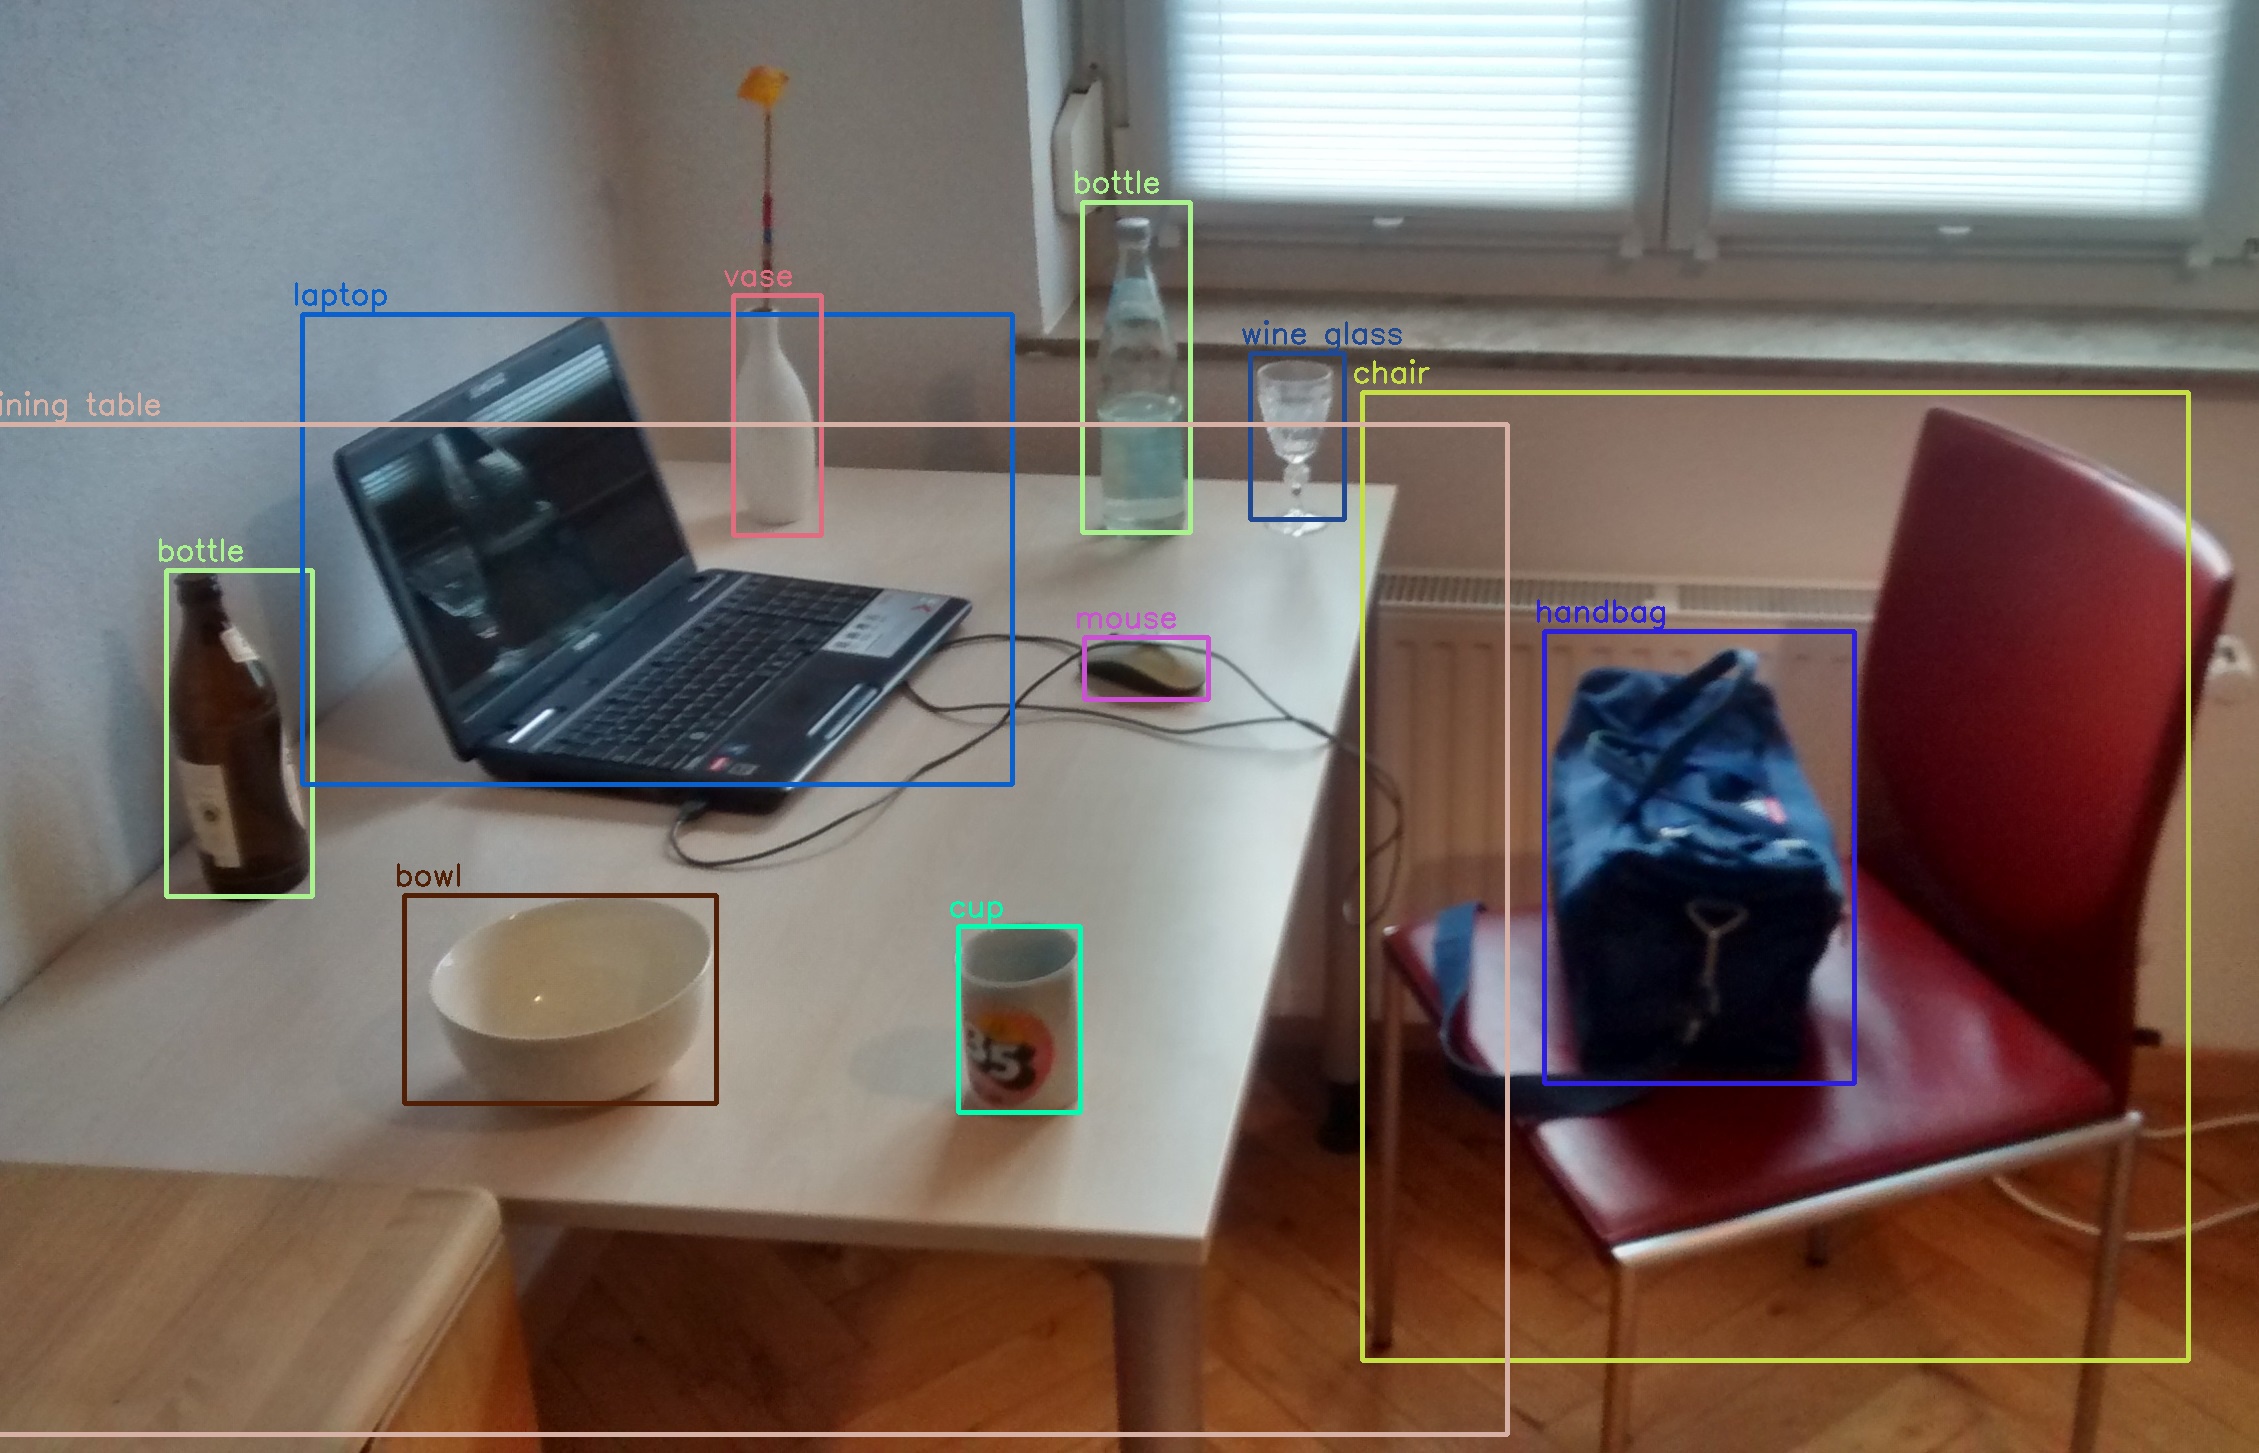
Object detection is the task of identifying and locating multiple objects within an image.

It builds on classification and localization.

  • Classification: assign one label to entire image.
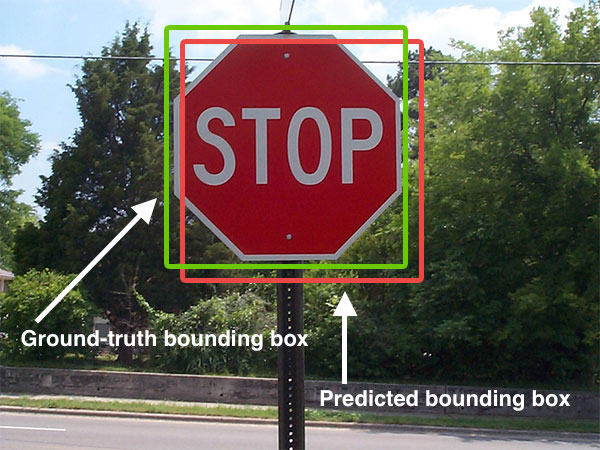
  • Localization: predicting a single bounding box for a specific class within the entire image.

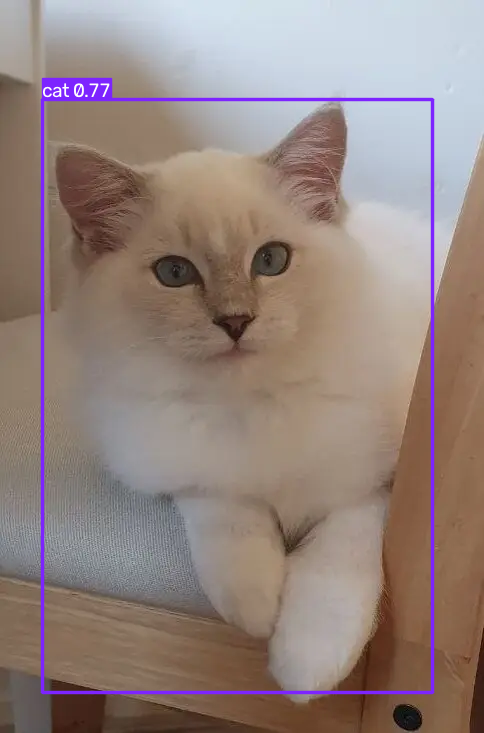
Outputs: bounding boxes + class labels + confidence scores
Why classification comes first

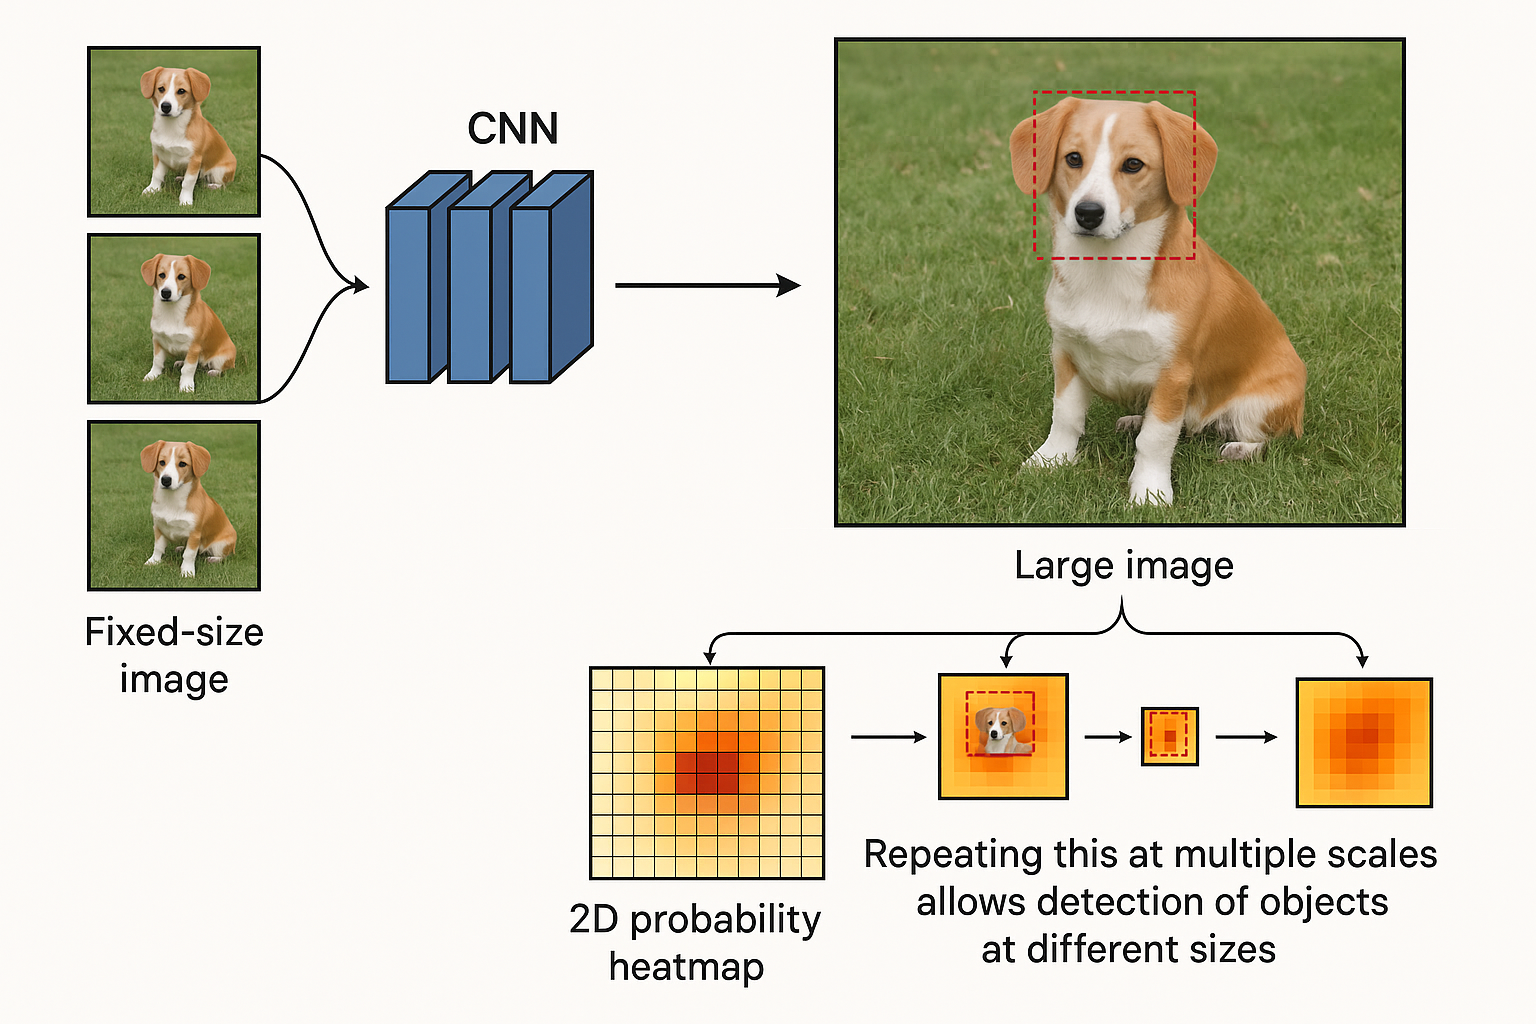
Early detection models relied on sliding-window classification, while some modern object detectors build upon pre-trained classification models.

Understanding object class features is the foundation for detection.
Challenges in object detection

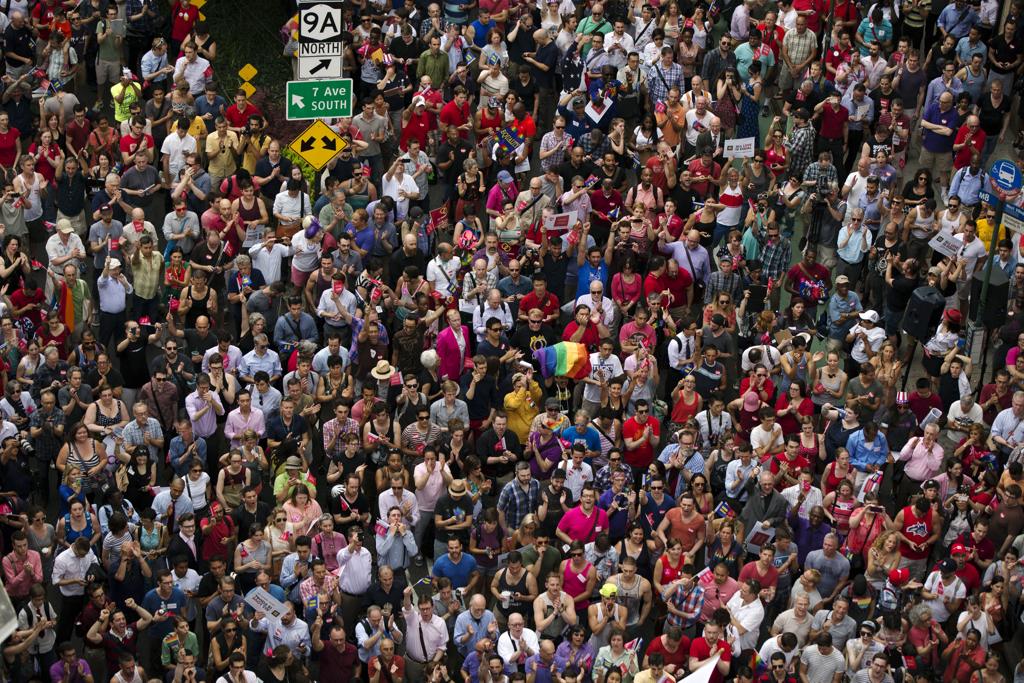
  • Scale variation: Objects may appear very small or very large, making it hard to capture all necessary details.

  • Occlusion and crowding: Objects can be partially blocked or tightly packed, creating ambiguous visual cues.

  • Background clutter: Busy or noisy backgrounds can mislead the detector and cause false positives.

  • Domain shift (lighting, camera, viewpoint, scene): Models trained in one setting may not generalize well to different environments.
Data formats

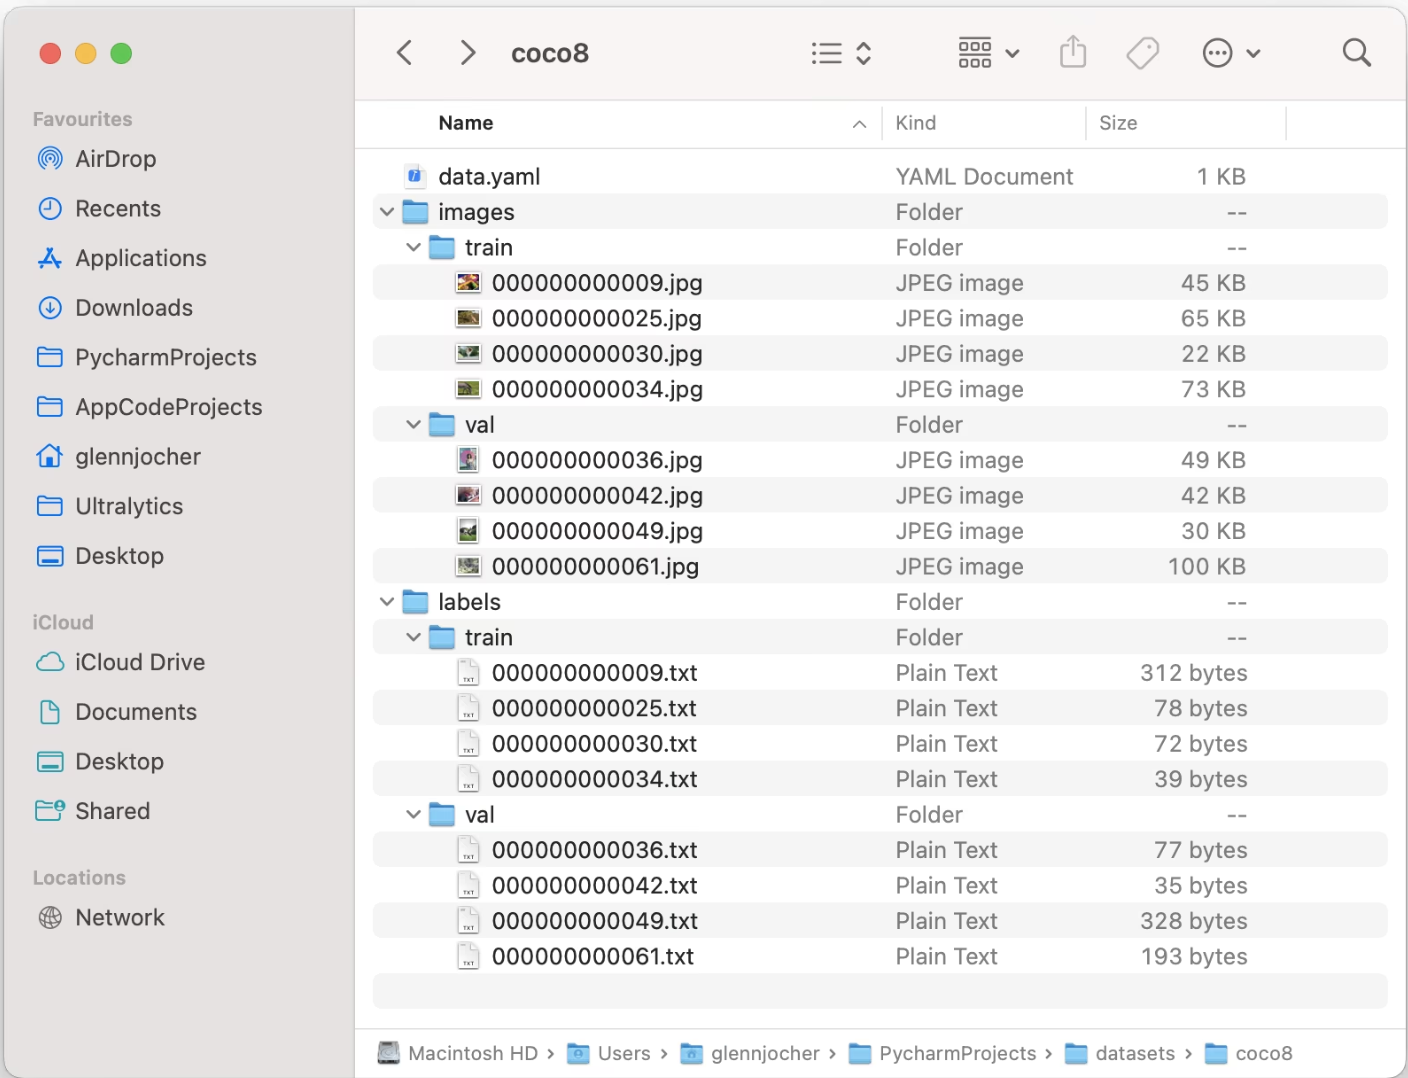
There are many formats for object detection datasets, with the most common being YOLO and COCO.

For training, we need the following:

  • Image path (input)

  • One or more bounding boxes, each containing:

    • (x, y, w, h), (x, y) can represent either the center or the top-left corner
    • Class label

YOLO format

  • Coordinates normalized to [0,1]
  • One line for one object
  • One .txt file per image (same file name)

<image_id>.txt:

class_id  x_center  y_center  width  height

COCO format

In the COCO format, all annotations are provided in a single JSON file.

  • images: contains id, file_name, width, height
  • annotations:
    • bbox = [x_min, y_min, width, height]
    • category_id
  • categories: list of object categories

Convert COCO to YOLO format

YOLO format is simpler to use when focusing on object detection, and the ultralytics library provides a convenient way to convert COCO annotations to YOLO format.

ultralytics <- import("ultralytics", convert = FALSE)
convert_coco <- ultralytics$data$converter$convert_coco
convert_coco(labels_dir = "path/to/coco/annotations/")

Evaluation metrics

Since we are now dealing with multiple class labels and need to assess how closely a bounding box matches the ground truth, the evaluation metrics become slightly more complex.

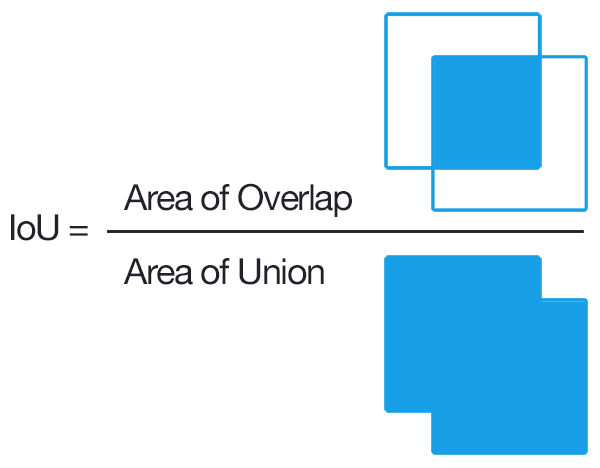
Intersection over Union (IoU) measures how well a predicted bounding box overlaps with the ground truth.
True positive and false positive

A true positive is a predicted bounding box that satisfies all of the following:

  • predicted class = ground truth class.
  • IoU \geq threshold (e.g., 0.5).
  • Each ground truth bounding box can be matched with at most one true positive prediction.

A false positive is a predicted bounding box that satisfies one of the following:

  • Predicted class \neq any ground truth class.
  • IoU < threshold for all ground truth boxes of that class.
  • The ground truth box has already been matched to another true positive prediction with higher confidence score.

True negative and false negative

In object detection, true negatives are usually not counted in standard metrics, because the background (areas with no object) is vast and not explicitly evaluated.

If a ground truth bounding box does not match any predicted bounding box, it is counted as a false negative.

Precision and recall

  • Precision: fraction of predicted boxes that are correct

\text{Precision} = \frac{TP}{TP + FP}

  • Recall: fraction of ground truth boxes that are detected

\text{Recall} = \frac{TP}{TP + FN}

Average precision

Average precision (AP) is the area under the precision-recall (PR) curve for a single class. The PR curve is obtained by plotting the model’s precision and recall values as a function of the model’s confidence score threshold.

Mean average precision (mAP) is the average of AP over all classes:

\text{mAP} = \frac{1}{K}\sum_{k=1}^{K}AP_k

It captures overall performance across all classes.

Two-stage detectors

The R-CNN family are two-stage detectors: propose ~2000 regions, then classify and refine each one.

  • Propose: Selective Search merges similar superpixels into ~2000 boxes, no learning.
  • Classify: a CNN, an SVM per class, and box regression score and tighten each crop.
  • Clean up: NMS drops overlapping boxes (IoU \geq threshold), keeping the best per object.
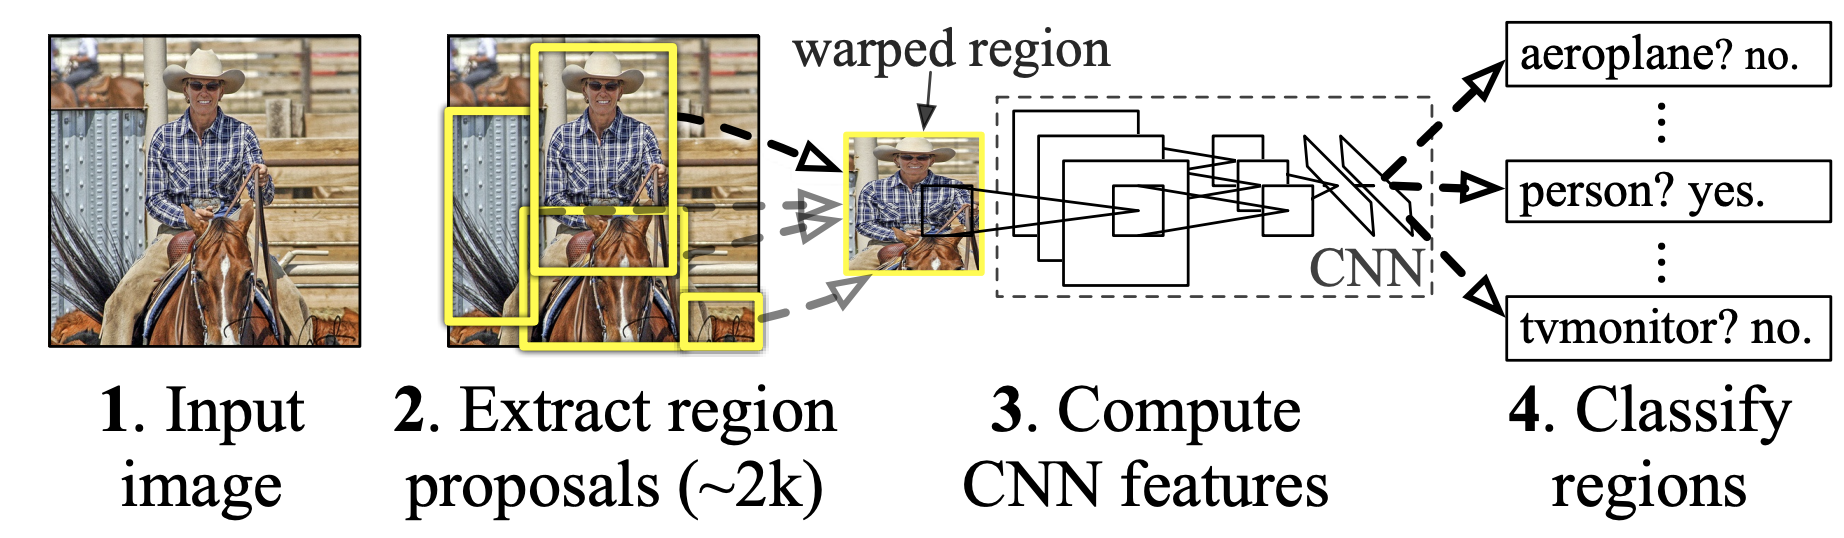
Fast R-CNN: one pass

R-CNN ran the CNN ~2000 times per image. Fast R-CNN runs it once.

  • One pass over the image → a shared feature map.
  • RoI pooling: each proposal → fixed 7 × 7 grid → one same-size vector.
  • One head predicts class scores + box offsets, trained end to end.
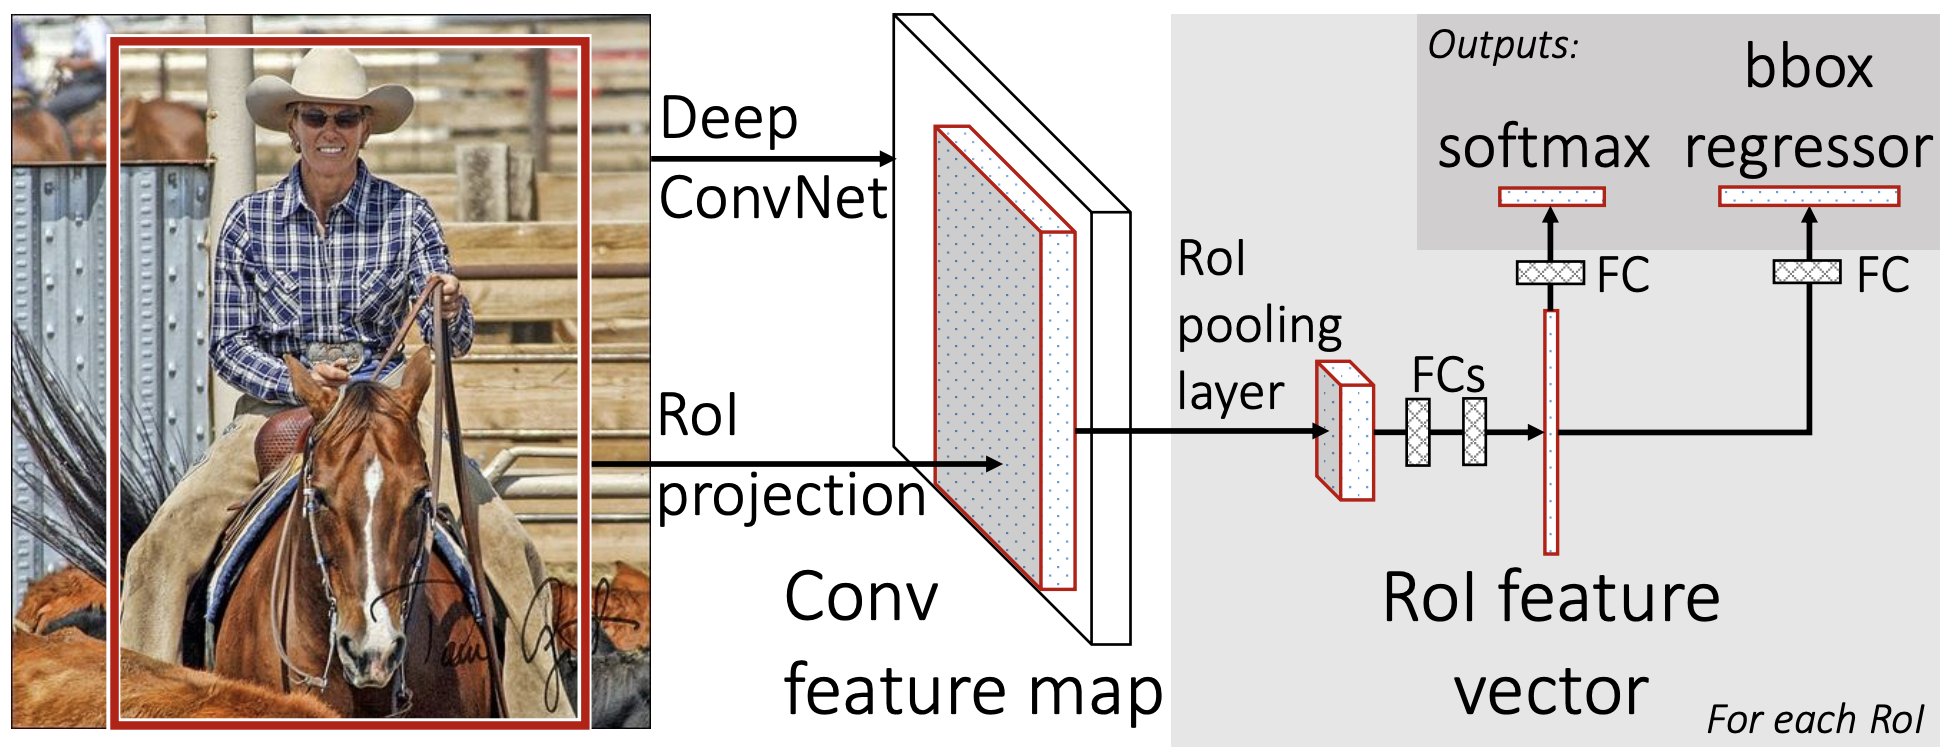
Faster R-CNN: learned proposals

Selective Search is a fixed, CPU-bound algorithm. Faster R-CNN learns the proposals instead.

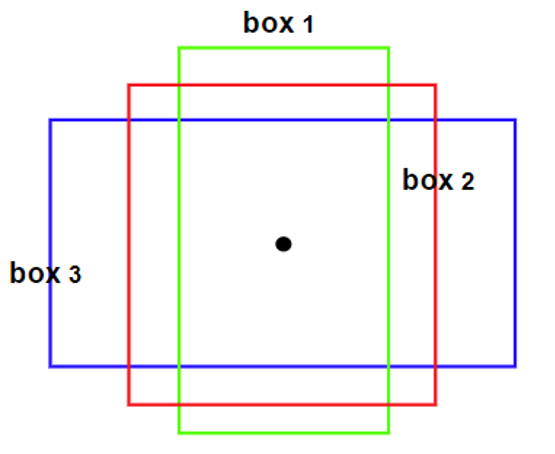
  • Anchors: predefined boxes of several scales and shapes at each feature-map position.
  • RPN: predicts 2k objectness scores and 4k offsets from those anchors → proposals.
  • Same RoI head as Fast R-CNN — but proposals and detection now train together.
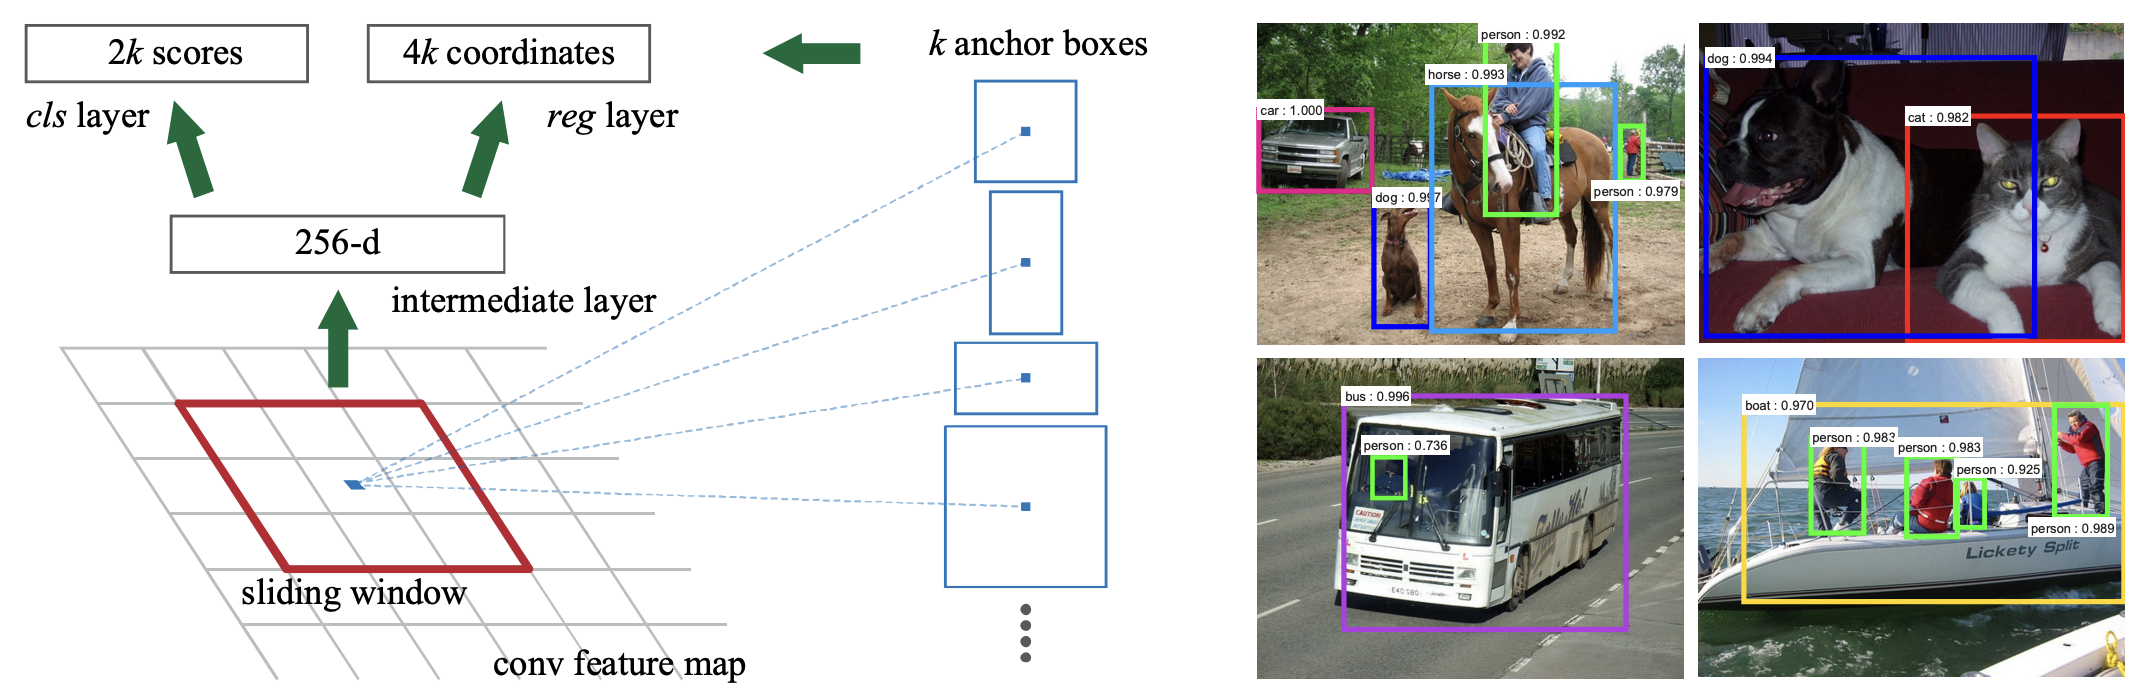
YOLO: one pass, many boxes

YOLO (“You Only Look Once”) is a single-stage detector that predicts all bounding boxes and class labels in a single pass, without a separate proposal stage. This makes it much faster than R-CNN, often at the cost of some accuracy.

  • Divide the image into a 7 × 7 grid. Each cell predicts 2 bounding boxes, each represented by (x, y, w, h, \text{confidence}), along with class probabilities.
  • Each cell is responsible for detecting the object whose centre falls within it, so it can detect at most one object.
  • Apply NMS to remove duplicate detections, just as in two-stage detectors.
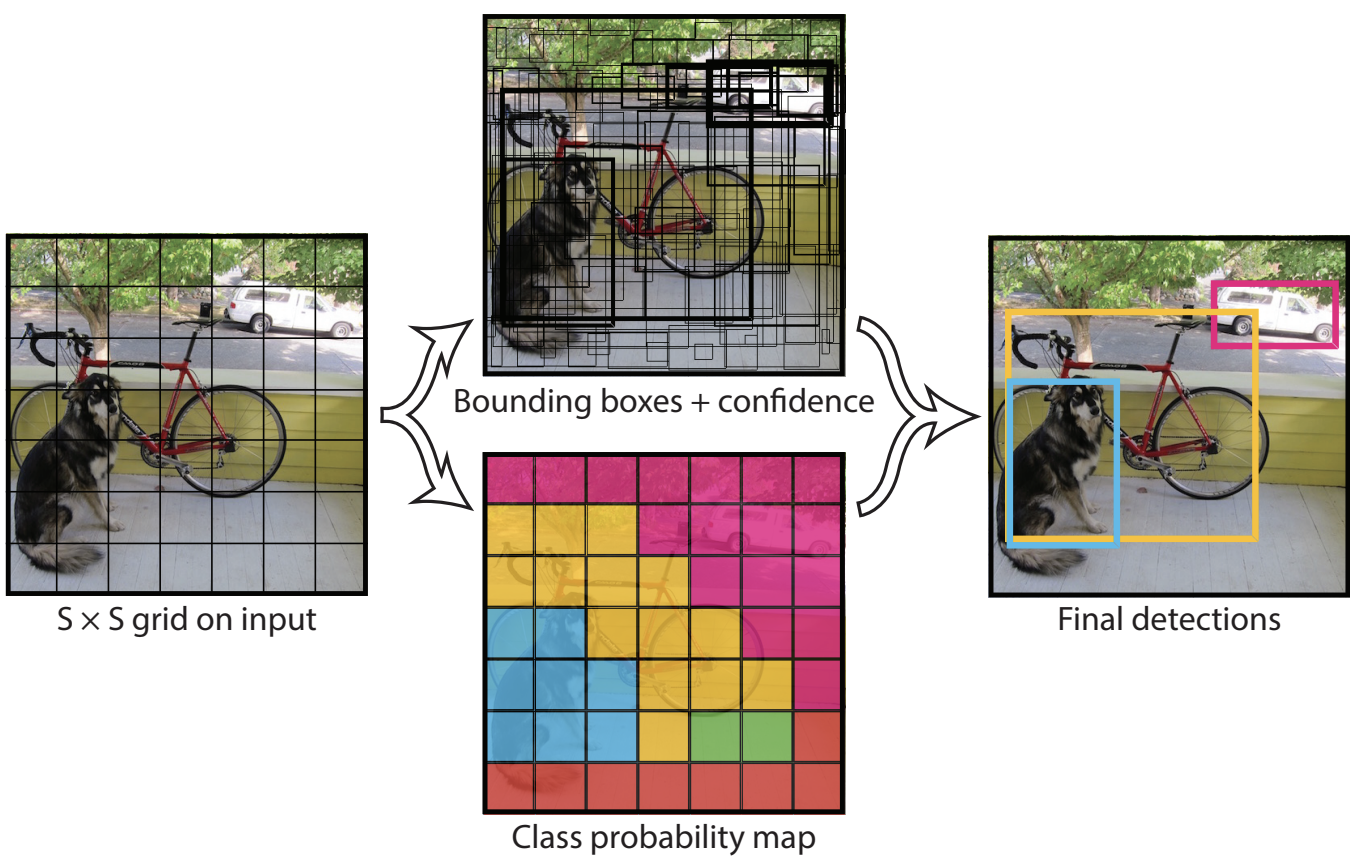
YOLOv2 and v3: same recipe, refined

Later versions retain the single-pass design while progressively addressing its limitations.

  • v2: introduces anchor boxes generated using k-means clustering on training-set bounding boxes, along with batch normalization and the Darknet-19 backbone.
  • v3: uses a Darknet-53 backbone with residual blocks and predicts at three scales. Fine grids capture small objects, while coarser grids capture larger ones. Features are also fused across scales.
  • Overall: significantly narrows the accuracy gap with two-stage detectors while retaining real-time inference speed.
The YOLO author left the field

After YOLOv3, Joseph Redmon stopped working on computer vision, citing military use and mass surveillance.

His YOLOv3 paper reads like a blog post rather than a paper:

I guess at least we know the technology is in good hands and definitely won’t be used to harvest your personal information and sell it to…. wait, you’re saying that’s exactly what it will be used for?? Oh.

As researchers we have a responsibility to at least consider the harm our work might be doing and think of ways to mitigate it. We owe the world that much.

The YOLO branding chaos

  • After Joseph Redmon left, the YOLO name continued to be used by various researchers, organizations, and companies.

  • Versions YOLOv4 to YOLOv7 were developed independently, each with their own modifications, training tricks, and implementations.

  • No central coordination led to confusion:

    • Hard to track which version was referenced
    • Differences in performance and reliability
    • Fragmented naming and forks
  • Ultralytics YOLOv8 resolved this:

    • Built entirely in PyTorch
    • Provides a clean, standardized, and accessible framework
    • Quickly became the dominant version in practice

YOLO code example

model <- ultralytics$YOLO("yolov8n.pt")
print(model$info())
YOLOv8n summary: 129 layers, 3,157,200 parameters, 0 gradients, 8.9 GFLOPs
(129, 3157200, 0, 8.8550912)
torchinfo$summary(model, verbose = 0L)
================================================================================
Layer (type:depth-idx)                                  Param #
================================================================================
YOLO                                                    --
├─DetectionModel: 1-1                                   --
│    └─Sequential: 2-1                                  --
│    │    └─Conv: 3-1                                   (464)
│    │    └─Conv: 3-2                                   (4,672)
│    │    └─C2f: 3-3                                    (7,360)
│    │    └─Conv: 3-4                                   (18,560)
│    │    └─C2f: 3-5                                    (49,664)
│    │    └─Conv: 3-6                                   (73,984)
│    │    └─C2f: 3-7                                    (197,632)
│    │    └─Conv: 3-8                                   (295,424)
│    │    └─C2f: 3-9                                    (460,288)
│    │    └─SPPF: 3-10                                  (164,608)
│    │    └─Upsample: 3-11                              --
│    │    └─Concat: 3-12                                --
│    │    └─C2f: 3-13                                   (148,224)
│    │    └─Upsample: 3-14                              --
│    │    └─Concat: 3-15                                --
│    │    └─C2f: 3-16                                   (37,248)
│    │    └─Conv: 3-17                                  (36,992)
│    │    └─Concat: 3-18                                --
│    │    └─C2f: 3-19                                   (123,648)
│    │    └─Conv: 3-20                                  (147,712)
│    │    └─Concat: 3-21                                --
│    │    └─C2f: 3-22                                   (493,056)
│    │    └─Detect: 3-23                                (897,664)
================================================================================
Total params: 3,157,200
Trainable params: 0
Non-trainable params: 3,157,200
================================================================================

YOLO prediction

result <- model$predict("slide_figures/original.png")

image 1/1 /Users/patrickli/Desktop/rproj/ssa-cv-workshop/instructor/slides/slide_figures/original.png: 640x448 1 cat, 35.0ms
Speed: 1.5ms preprocess, 35.0ms inference, 0.7ms postprocess per image at shape (1, 3, 640, 448)
result[0]$save("slide_figures/cat_object_detect.png")
'slide_figures/cat_object_detect.png'

YOLO training config file (data.yaml)

data.yaml:

# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# COCO8 dataset (first 8 images from COCO train2017) by Ultralytics
# Documentation: https://docs.ultralytics.com/datasets/detect/coco8/
# Example usage: yolo train data=coco8.yaml
# parent
# ├── ultralytics
# └── datasets
#     └── coco8 ← downloads here (1 MB)

# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: coco8 # dataset root dir
train: images/train # train images (relative to 'path') 4 images
val: images/val # val images (relative to 'path') 4 images
test: # test images (optional)

# Classes
names:
  0: person
  1: bicycle
  2: car
  3: motorcycle
  4: airplane
  5: bus
  6: train
  7: truck
  8: boat
  9: traffic light
  10: fire hydrant
  11: stop sign
  12: parking meter
  13: bench
  14: bird
  15: cat
  16: dog
  17: horse
  18: sheep
  19: cow
  20: elephant
  21: bear
  22: zebra
  23: giraffe
  24: backpack
  25: umbrella
  26: handbag
  27: tie
  28: suitcase
  29: frisbee
  30: skis
  31: snowboard
  32: sports ball
  33: kite
  34: baseball bat
  35: baseball glove
  36: skateboard
  37: surfboard
  38: tennis racket
  39: bottle
  40: wine glass
  41: cup
  42: fork
  43: knife
  44: spoon
  45: bowl
  46: banana
  47: apple
  48: sandwich
  49: orange
  50: broccoli
  51: carrot
  52: hot dog
  53: pizza
  54: donut
  55: cake
  56: chair
  57: couch
  58: potted plant
  59: bed
  60: dining table
  61: toilet
  62: tv
  63: laptop
  64: mouse
  65: remote
  66: keyboard
  67: cell phone
  68: microwave
  69: oven
  70: toaster
  71: sink
  72: refrigerator
  73: book
  74: clock
  75: vase
  76: scissors
  77: teddy bear
  78: hair drier
  79: toothbrush

# Download script/URL (optional)
download: https://github.com/ultralytics/assets/releases/download/v0.0.0/coco8.zip

YOLO training

model$train(
    data = 'data.yaml',   # dataset config (train/val paths + class names)
    epochs = 100L,        # number of epochs
    imgsz = 640L,         # image size (square)
    batch = 16L,          # batch size
    lr0 = 0.01,           # inital learning rate
    optimizer = 'auto',   # optimizer: e.g. 'SGD', 'Adam'
    device = NULL,        # device: 'cpu', '0', '0,1', etc.
    workers = 8L,         # dataloader workers
    project = 'runs/train', # save path
    name = 'exp',         # folder name
    exist_ok = FALSE,     # overwrite existing folder
    pretrained = TRUE,    # use pretrained weights if True
    patience = 50L,       # early stopping patience
    save = TRUE,          # save final model
    save_period = 10L,    # save every N epochs (-1 = disabled)
    seed = 0,             # random seed
    verbose = TRUE,       # print progress
)

YOLO live camera demo

model$predict(source = 0L, show = TRUE)
  1. Camera Capture:

    • A webcam (built-in or external) provides live video frames.
    • OpenCV (cv2.VideoCapture) continuously reads frames from the camera.
  2. Object Detection: YOLO predicts the objects in the frame, providing class labels and bounding boxes.

  3. Display: Bounding boxes and labels are drawn on the frame by OpenCV in real time.

Exercises (07-detection-sol.R)